Introduction
Artificial intelligence (AI) is transforming industries through machine learning, generative AI, and large language models (LLMs). However, faster processors alone cannot guarantee better AI performance. One major challenge is moving data between memory and computing units efficiently.
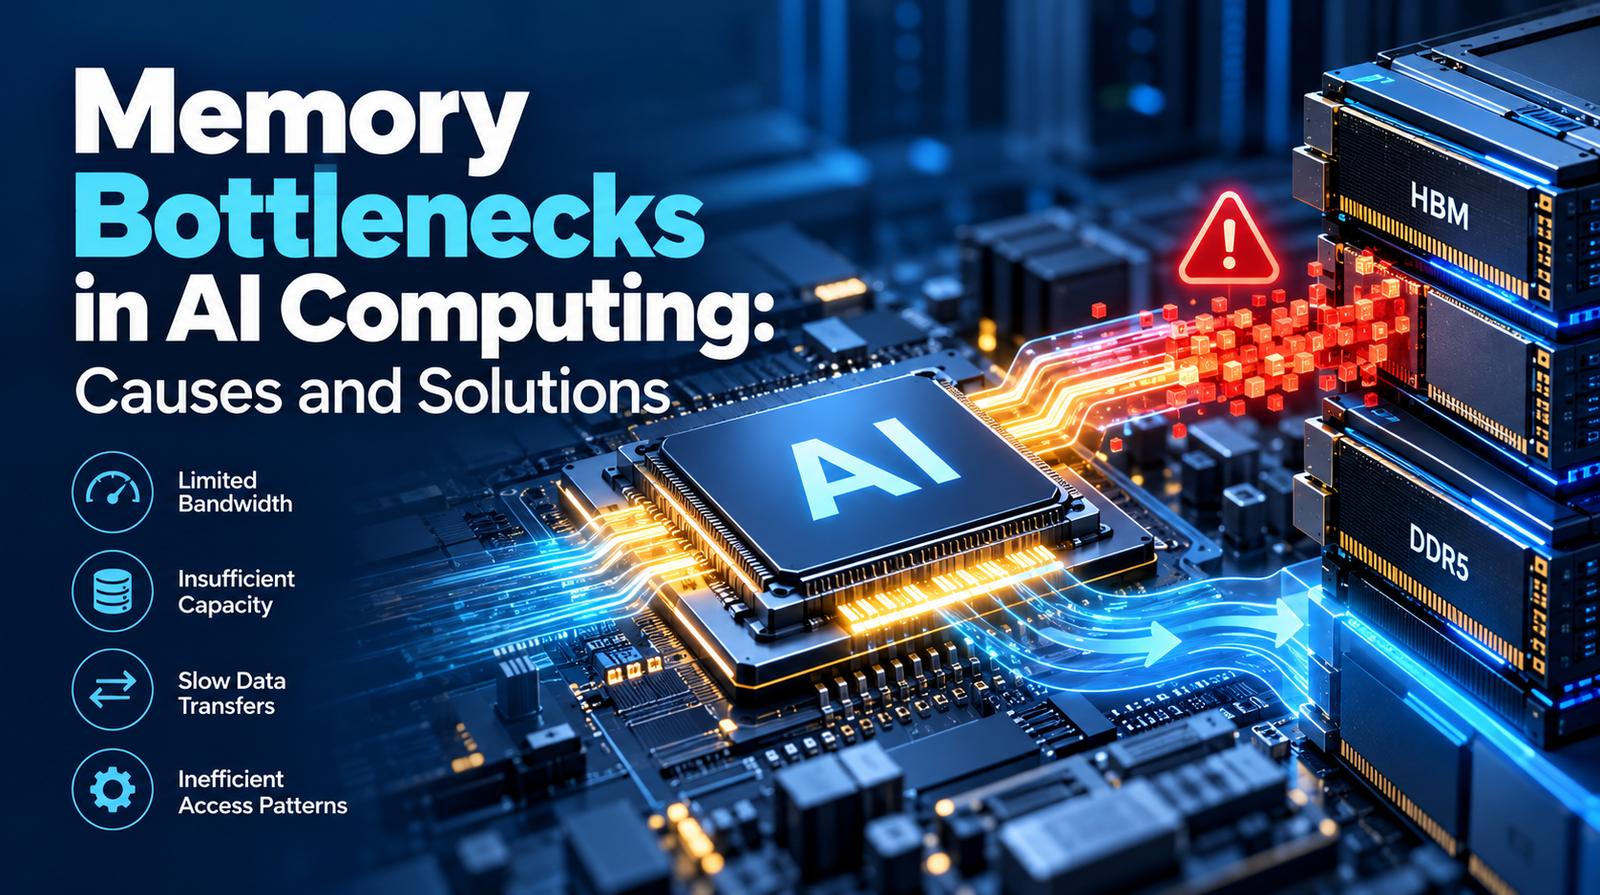
This challenge is known as a memory bottleneck in AI computing. It occurs when a processor must wait for data to arrive from memory before it can continue processing. As AI models grow larger, moving data efficiently becomes increasingly important.
Modern AI systems rely on GPUs, high-bandwidth memory (HBM), and advanced memory architectures to handle demanding workloads. Even with powerful hardware, limited memory bandwidth, insufficient capacity, and inefficient data transfers can reduce performance.
Understanding the causes of memory bottlenecks helps engineers, developers, and hardware professionals design faster and more efficient AI systems. This article explores the main causes, their impact, and practical solutions.
What Is a Memory Bottleneck in AI Computing?
A memory bottleneck occurs when an AI processor cannot access the data it needs quickly enough to maintain its potential processing speed.
AI workloads require frequent access to model parameters, input datasets, intermediate calculations, and generated outputs. If memory cannot supply this information at the required rate, the processor may remain underutilized.
For example, an AI model may run on a high-performance GPU capable of performing billions of calculations per second. However, if the GPU spends too much time waiting for data from memory, the application may perform below its expected capability.
This problem is often described as the memory wall: computing performance improves faster than certain aspects of memory performance, creating a growing gap between processing power and data delivery.
Memory bottlenecks can affect AI training, model inference, recommendation systems, image recognition, and other data-intensive applications.
Why Memory Matters in AI Computing
AI models process large amounts of data during training and inference. Their performance depends not only on processing speed but also on how quickly data can move through the system.
Memory plays several important roles:
- Model storage: Holds model weights and parameters required for AI computations.
- Data processing: Supplies input data and stores intermediate results.
- Memory bandwidth: Determines how much data can move between memory and the processor per second.
- Memory capacity: Limits how much data and how many model components can remain available in fast memory.
- Temporary storage: Stores intermediate activations and attention-related information during model execution.
When these resources cannot keep up with the workload, AI performance may decline even when the processor has unused computing capacity.
According to NVIDIA’s CUDA Best Practices Guide, effective memory optimization involves improving bandwidth utilization, minimizing unnecessary data transfers, and arranging memory accesses efficiently.
1. Major Causes of Memory Bottlenecks in AI Computing
1.1 Limited Memory Bandwidth
Memory bandwidth measures how much data can be transferred between memory and a processor within a given period.
AI workloads frequently move large volumes of data. When memory bandwidth is insufficient, the processor must wait for the required information instead of performing additional calculations.
This issue is particularly important when running large language models. During token generation, a model may repeatedly read its weights to produce the next token. If the system cannot supply those weights quickly enough, memory bandwidth can limit performance.
Solution: Use hardware with suitable memory bandwidth, optimize data access patterns, and reduce unnecessary memory traffic. High-bandwidth memory can help demanding AI workloads when bandwidth is a limiting factor.
1.2 Insufficient Memory Capacity
Memory capacity determines how much information a system can hold at once.
Large AI models may require substantial memory for model weights, activations, temporary tensors, and other data structures. During LLM inference, memory is also needed for the key-value (KV) cache, which stores information from previous tokens to support subsequent generation.
When the required data exceeds available GPU memory, a system may need to divide the workload across multiple GPUs, transfer data between system RAM and GPU memory, or use other memory-management strategies.
These approaches can introduce additional complexity and data-transfer overhead.
Solution: Select a GPU with sufficient memory capacity, reduce model memory requirements where appropriate, and optimize how data is stored. Quantization and efficient attention implementations can reduce memory consumption for supported workloads.
1.3 Slow Data Transfers Between CPU and GPU
AI applications often use both CPU memory and GPU memory. Moving data between them can introduce delays, particularly when large datasets are repeatedly transferred during computation.
For example, an application that continuously copies input batches from system RAM to GPU memory may spend valuable time transferring data rather than processing it.
The impact depends on the hardware interconnect, transfer size, synchronization, and workload design.
Solution: Keep frequently accessed data on the GPU when practical, minimize unnecessary transfers, and use asynchronous data transfers to overlap data movement with computation where supported.
1.4 Inefficient Memory Access Patterns
How a program accesses memory can affect its effective bandwidth.
If GPU threads access scattered or poorly aligned memory locations, the hardware may need additional memory transactions to retrieve the requested data. This can waste bandwidth and reduce performance.
Repeatedly loading the same data can also create unnecessary memory traffic.
Solution: Arrange data to support efficient access patterns, combine compatible memory operations where appropriate, and reduce redundant data reads. In CUDA applications, coalesced global-memory accesses are an important optimization technique.
1.5 Growing AI Model Sizes
Modern AI applications increasingly use models with large parameter counts, longer context windows, and more demanding workloads.
As models grow, their memory requirements also increase. Larger models may need more space for weights, intermediate activations, and attention caches.
Long-context LLM applications are particularly challenging because the amount of information maintained in the KV cache can grow as the conversation or input sequence becomes longer.
Solution: Apply model quantization, efficient attention algorithms, cache management, and suitable model-serving strategies. The best approach depends on the model architecture, accuracy requirements, and available hardware.
1.6 Memory Contention in Multi-GPU Systems
Large AI workloads are often distributed across multiple GPUs. These systems must exchange model parameters, activations, gradients, or other intermediate data.
When several devices compete for shared communication resources, or when inter-GPU transfers become too frequent, data movement can limit overall performance.
Solution: Optimize workload distribution, reduce unnecessary communication, and select suitable interconnects and parallelization strategies. Engineers should measure both memory bandwidth and inter-GPU communication performance when diagnosing these systems.
2. How Memory Bottlenecks Affect AI Performance
Memory bottlenecks can influence several important performance metrics.
Slower AI Model Training
During training, AI systems repeatedly process datasets and update model parameters. If data cannot be supplied quickly enough, GPUs may remain underutilized.
This can increase training time and reduce the amount of work completed within a given computing budget.
Higher Inference Latency
Inference is the process of using a trained model to generate predictions or responses.
For LLMs, memory limitations can affect how quickly individual tokens are generated. This can increase response times in chatbots, coding assistants, and other interactive AI applications.
Lower Throughput
Throughput measures how much work a system completes within a specific period.
When memory bandwidth or capacity becomes a limiting factor, a server may process fewer requests or generate fewer tokens per second than expected.
Increased Infrastructure Costs
Memory inefficiencies can force organizations to use additional GPUs, distribute models across more devices, or invest in higher-capacity hardware.
Optimizing memory usage can improve hardware utilization and help reduce the computing resources required for a given workload.
However, memory optimization does not always eliminate the need for additional hardware. Some applications have genuine capacity or bandwidth requirements that exceed the limits of a particular system.
3. Practical Solutions to Memory Bottlenecks in AI Computing
Addressing memory bottlenecks requires a combination of hardware selection, software optimization, and efficient system architecture.
3.1 Use High-Bandwidth Memory
High-bandwidth memory (HBM) is designed to provide high data-transfer rates for demanding computing workloads.
Unlike conventional memory configurations, HBM uses vertically stacked memory dies and a wide interface to support high bandwidth within a compact physical footprint.
HBM is widely used in advanced AI accelerators where moving large amounts of data quickly is essential.
Key benefits of HBM include:
- High memory bandwidth for data-intensive workloads.
- Improved support for large-scale AI computations.
- Efficient integration with suitable processors and accelerators.
- Potential improvements in performance per watt for supported workloads.
However, HBM is not the only factor determining AI performance. Memory capacity, processor architecture, software efficiency, and data movement must also be considered.
3.2 Optimize AI Models Through Quantization
Quantization reduces the numerical precision used to represent model weights and, in some implementations, activations.
For example, a model may use 16-bit floating-point values instead of 32-bit floating-point values. Lower-precision formats can reduce memory requirements and data movement.
More aggressive quantization techniques can reduce storage requirements further, depending on the selected format.
Benefits of quantization include:
- Reduced model memory consumption.
- Lower memory bandwidth requirements in suitable workloads.
- Potentially faster inference.
- The ability to deploy larger models on memory-constrained hardware.
However, lower precision can affect model accuracy. Developers should evaluate output quality, latency, and throughput before deploying a quantized model in production.
3.3 Improve Memory Access Patterns
Software optimization is another important way to address memory bottlenecks.
Developers should examine how their applications read, write, and reuse data. Efficient access patterns can reduce unnecessary memory transactions and improve effective bandwidth.
Useful techniques include:
- Coalescing GPU memory accesses.
- Reusing data through appropriate cache strategies.
- Reducing redundant memory operations.
- Using shared memory for suitable workloads.
- Optimizing tensor layouts and computation kernels.
These techniques are particularly relevant when developing custom GPU kernels or optimizing deep learning frameworks.
3.4 Reduce Unnecessary CPU-GPU Transfers
Repeated transfers between system RAM and GPU memory can introduce additional latency and consume interconnect bandwidth.
Developers can reduce this overhead by keeping frequently used data on the GPU when practical.
Other techniques include asynchronous transfers, pinned host memory where appropriate, and overlapping data transfers with computation.
For example, a training pipeline can prepare the next batch while the GPU processes the current batch. This approach may improve hardware utilization when data preparation and transfer are limiting factors.
3.5 Optimize Attention and KV Cache Management
Large language models use attention mechanisms to process relationships between tokens.
During autoregressive generation, the KV cache stores key and value tensors from previous tokens. This reduces the need to recompute information for every new token, but the cache can consume substantial GPU memory as context lengths and concurrent requests increase.
Several techniques can help manage this overhead:
PagedAttention: Organizes KV cache storage into manageable blocks, helping reduce memory fragmentation and improve memory utilization in supported serving systems.
FlashAttention: Uses an IO-aware attention algorithm to reduce data movement between different levels of the GPU memory hierarchy.
KV cache quantization: Stores cache values using lower precision, potentially reducing memory consumption.
Efficient batching: Processes multiple requests together to improve resource utilization, subject to available memory and workload characteristics.
These methods address different aspects of memory efficiency. The best choice depends on the model, inference framework, hardware, and target workload.
3.6 Use Memory Profiling and Performance Monitoring
Memory optimization should begin with measurement rather than assumptions.
A system that appears slow may be limited by memory bandwidth, memory capacity, computation, data loading, or inter-GPU communication.
Developers can use profiling tools to identify the actual bottleneck.
Useful measurements include:
- GPU memory utilization.
- Effective memory bandwidth.
- GPU compute utilization.
- Memory allocation and transfer patterns.
- Cache performance and memory-access efficiency.
- Inference latency and tokens generated per second.
Tools such as NVIDIA Nsight Systems and Nsight Compute can help developers investigate GPU performance and identify opportunities for optimization.
After making changes, developers should benchmark the application again to confirm whether the optimization improved the intended performance metric.
4. Memory Bandwidth vs Memory Capacity: Understanding the Difference
Memory bandwidth and memory capacity are related, but they solve different problems.
| Feature | Memory Bandwidth | Memory Capacity |
|---|---|---|
| Meaning | How quickly data moves | How much data can be stored |
| Common unit | GB/s or TB/s | GB or TB |
| Main concern | Data-transfer speed | Available storage space |
| AI performance impact | Can limit processing throughput | Can limit model size and batch size |
| Possible solution | Higher-bandwidth memory and efficient access patterns | More memory or reduced memory requirements |
For example, a GPU may have enough memory capacity to hold an AI model but still generate responses slowly because it cannot move the required data quickly enough.
Conversely, a GPU may offer excellent memory bandwidth but lack enough capacity to hold the model and its associated data.
Therefore, selecting AI hardware requires evaluating both factors rather than focusing on memory size alone.
5. The Role of Emerging Memory Technologies
As AI workloads become more demanding, hardware manufacturers and researchers continue to explore new ways to improve memory capacity, bandwidth, and data movement.
Several technologies are worth understanding.
High-Bandwidth Memory
HBM remains important for AI accelerators that need to move large volumes of data at high speeds. Newer HBM generations aim to improve bandwidth and capacity, subject to the specifications of individual products.
Compute Express Link (CXL)
CXL is an interconnect technology that supports communication between processors, memory, and compatible devices.
Depending on the system architecture, CXL can enable memory expansion and resource sharing. It may help applications that need additional memory capacity, although expanded memory is not necessarily as fast as local GPU memory.
Processing-in-Memory
Processing-in-memory (PIM) brings certain computing operations closer to where data is stored.
The goal is to reduce the amount of data that must move between memory and separate processing units. This approach may benefit workloads where data movement consumes substantial time or energy.
However, practical benefits depend on the supported operations, implementation, and software ecosystem.
Advanced Memory Packaging
Advanced packaging technologies help integrate processors, memory, and other components into increasingly sophisticated systems.
These approaches can improve connectivity and support higher-bandwidth designs. Their effectiveness also depends on thermal management, manufacturing complexity, power delivery, and system-level architecture.
Together, these developments highlight an important direction in AI hardware: improving data movement is becoming just as important as increasing raw computing power.
6. Best Practices for Preventing Memory Bottlenecks
Organizations can take several practical steps to improve memory efficiency in AI systems.
- Choose hardware carefully: Evaluate memory capacity, bandwidth, processor performance, and interconnect capabilities against actual workload requirements.
- Profile before optimizing: Identify whether the application is memory-bound, compute-bound, or limited by another system component.
- Reduce unnecessary data movement: Minimize redundant transfers between the CPU, GPU, and other memory resources.
- Optimize model precision: Evaluate quantization and lower-precision computation where accuracy requirements permit.
- Improve memory reuse: Structure algorithms to reuse data efficiently and reduce repeated memory accesses.
- Manage inference memory: Optimize KV cache allocation, batch sizes, and context lengths according to workload requirements.
- Monitor performance continuously: Track latency, throughput, memory utilization, and effective bandwidth after deployment.
- Evaluate the complete system: Consider storage, networking, memory, and processing together instead of optimizing a single component in isolation.
Following these practices helps developers make informed decisions and improve the efficiency of existing AI infrastructure.
7. What Is the Future of Memory Optimization in AI?
The future of AI performance will depend on improvements across the entire computing system.
Faster accelerators will remain important, but they cannot eliminate every memory bottleneck. As AI models and context windows grow, developers must also improve memory efficiency and reduce unnecessary data movement.
Several developments are likely to remain important:
- Higher-bandwidth memory for AI accelerators.
- More efficient model compression and quantization.
- Improved attention algorithms and KV cache management.
- Better integration between processors and memory.
- Memory expansion and resource-sharing technologies.
- More advanced profiling and workload optimization tools.
These approaches are complementary rather than interchangeable. Hardware improvements provide additional capabilities, while software optimization helps applications use those capabilities efficiently.
For hardware engineers, developers, and infrastructure teams, understanding memory behavior will remain essential when designing and deploying large-scale AI applications.
Conclusion
Memory bottlenecks in AI computing occur when memory capacity, bandwidth, or data-transfer efficiency prevents processors from operating at their full potential.
Common causes include limited memory bandwidth, insufficient capacity, inefficient access patterns, CPU-GPU transfer overhead, growing model sizes, and communication overhead in multi-GPU systems.
Solutions include using suitable high-bandwidth memory, optimizing model precision, improving memory access patterns, reducing unnecessary transfers, and managing attention caches efficiently.
The key takeaway is that AI performance depends on more than processing power. Efficient memory utilization and data movement are equally important when building reliable, scalable, and cost-effective AI systems.
As AI workloads continue to evolve, memory optimization will remain a critical consideration for the next generation of computing hardware.
Frequently Asked Questions (FAQs)
1. What is a memory bottleneck in AI computing?
A memory bottleneck occurs when a processor cannot access or transfer data quickly enough to maintain its potential performance. It can reduce GPU utilization, increase latency, and limit AI workload throughput.
2. Why do AI models require high-bandwidth memory?
AI models frequently access large amounts of parameters, intermediate tensors, and other data. High-bandwidth memory helps supply data at high rates, supporting demanding workloads when memory bandwidth is a limiting factor.
3. How does memory bandwidth affect AI performance?
Memory bandwidth determines how quickly data can move between memory and the processor. Insufficient bandwidth can force processors to wait for data, reducing training efficiency or inference throughput.
4. Can quantization reduce AI memory bottlenecks?
Yes. Quantization can reduce model storage requirements and memory traffic by using lower-precision representations. Its benefits depend on the model, implementation, hardware, and accuracy requirements.
5. What is the difference between HBM and DDR memory?
HBM uses stacked memory dies and a wide interface to provide high bandwidth, making it useful for demanding AI accelerators. DDR memory is commonly used as system memory in computers and servers. Their performance, capacity, cost, and integration characteristics differ.
6. How can developers identify memory bottlenecks?
Developers can use profiling tools to measure memory bandwidth, GPU utilization, data transfers, allocation behavior, and application latency. These measurements help distinguish memory limitations from compute or communication bottlenecks.